Next-Gen AI Model Governance

Govern Every Model
from Gate to Production

With ModelArcs, operationalize your ML Engineering. Connect model artifacts, validation evidence, automated deployment gateways, and retirement tracking in one accountable lifecycle platform.

Integrated with Enterprise ML Infrastructure
TRACE LIFECYCLE • MODELARCS PLATFORM •
ML Engineer MLOps Architect Risk Officer
1,250+

Active production models
under automated governance

Zero-Drift
Deployment
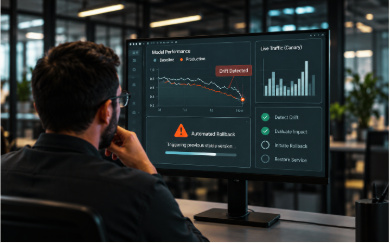
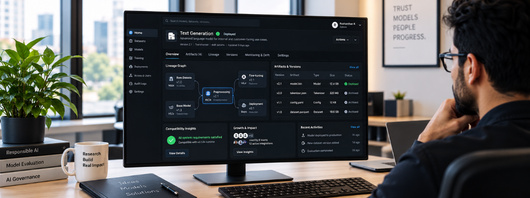
ML engineer monitoring the global model fleet
audit compliance 99.8%
validation runs
passed
14K
peak throughput 5,8K rps
ML engineering team reviewing the ModelArcs lifecycle dashboard
Core Platform Architecture

Core Platform Capabilities

ModelArcs brings the model lifecycle into one connected operational layer, giving teams a clearer view of every model, decision, deployment, issue, and dependency from development through retirement.

End-to-End Model Registry

Know every model. Understand its journey.

End-to-End Model Registry

Validation & Release Gateway

Turn model readiness into a visible, accountable decision.

Validation and Release Gateway

Controlled Release & Deployment

Move from approved model to production without losing the thread.

Controlled Release and Deployment
Live Architecture Walkthrough

See ModelArcs In Action

Watch how enterprise AI engineering teams register models, validate neural pipelines against automated gates, and deploy with zero drift in our unified control plane.

Watch architecture walkthrough See ModelArcs in action
A Connected Lifecycle

A Clearer Way to Operate

Stage 01: Registry

Development & Context

End-to-End Model Registry

Create a structured source of truth for models, owners, versions, artifacts, intended use, dependencies, and lifecycle status so teams can quickly understand what is running, who owns it, and where it fits.

Stage 02: Validation

Evaluation & Compliance

Validation & Release Gateway

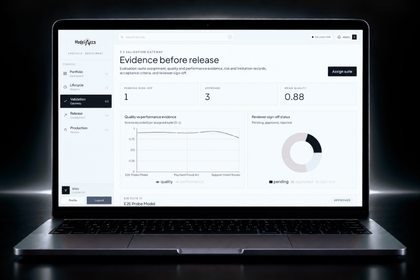
Connect evaluation evidence, acceptance criteria, risk considerations, reviewer decisions, and release approvals in one workflow so teams can move models forward with the reasoning behind each decision still accessible.

Stage 03: Release

Deployment & Progress

Controlled Release & Deployment

Coordinate release packages, target environments, deployment progress, approvals, exceptions, and rollback preparation from a shared operational workspace.

Stage 04: Production

Oversight & Review

Production Performance Review

Deployment is not the finish line. Review model performance, drift, incidents, feedback, and remediation decisions so production models stay connected to ongoing operational oversight.

Stage 05: Retirement

Safe De-provisioning

Lifecycle & Retirement Guardrails

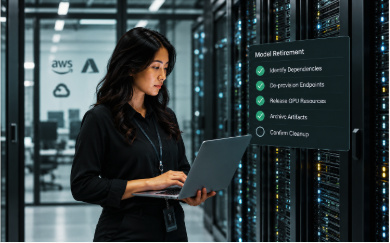
When a model reaches the end of its useful life, understand its dependencies, consuming services, outstanding actions, and retirement status before it is removed from operation.

Enterprise advisor reviewing ModelArcs compliance and lifecycle value
Enterprise Value & Compliance

Why Choose ModelArcs for
Your Enterprise ML Operations?

ModelArcs provides a centralized operational record where ML engineering, MLOps, model risk, and enterprise governance teams collaborate with full transparency, accountability, and speed.

100% Traceable Lineage
10x Faster Audit Sign-off
Interactive Platform Console

Explore the
ModelArcs Workspace

Explore Console
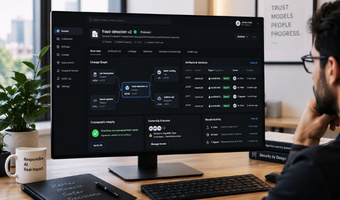
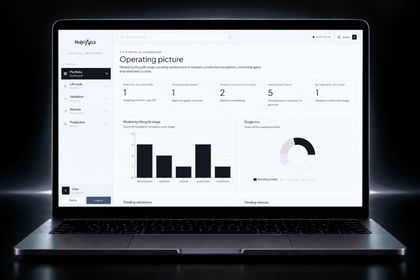
ModelArcs workspace Operating picture on a laptop
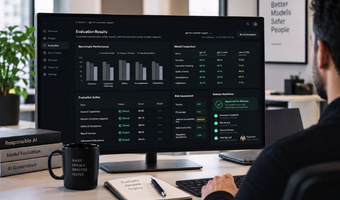
ModelArcs workspace Evidence before release on a laptop

Operating picture

See models by lifecycle stage, pending validations, production exceptions, and overdue gates in one connected operating picture.

Transparent & Predictable Pricing

Simple Pricing for Fast-Moving
ML Engineering Teams

No surprise overage fees. Scale from your first central model registry to multi-region canary gates with complete governance.

Squad

Starter

Centralize model registry and container pinning for agile ML squads.

$ 199 /mo
Billed monthly
Start 14-Day Free Trial
Includes:
  • Up to 25 Active Models in Registry
  • 3 Automated Validation Deployment Gates
  • Git Hash & Docker Container Fingerprinting
  • Slack & Webhook Drift Threshold Alerts
  • Community & Standard Support (24h SLA)
Dedicated

Air-Gapped

On-premises and dedicated VPC deployment for heavily regulated sectors.

Custom
Custom multi-year or annual contract
Talk to Solutions Architect
Mission-Critical Capabilities:
  • On-Premises, AWS Outposts & Air-Gapped Helm
  • Hardware-Enforced Cryptographic Evidence Vault
  • Custom Regulatory & EU AI Act Governance Adapters
  • 99.99% Uptime SLA with Dedicated Lead Architect
  • Custom Infosec Review & Security Attestations
Industry Validation

Validated by
ML Engineering Leaders

Discover how forward-thinking enterprise AI teams rely on ModelArcs for operational clarity and compliance.

5.0

"ModelArcs eliminated our biggest MLOps blind spot. Connecting validation evidence directly to deployment gates reduced our risk review cycles from weeks to minutes."

5.0

"The retirement and dependency tracking alone saved us countless cloud GPU hours by cleanly de-provisioning stale model services without breaking downstream endpoints."

5.0

"With ModelArcs' automated evaluation gateway, our regulatory model risk audit preparation dropped from three weeks to under 48 hours without compromising governance standards."

5.0

"The real-time drift telemetry and instant canary rollback saved our live perception pipeline during a silent upstream feature corruption. It caught the drift in sub-seconds before any client impact."

ML Engineering Insights

From the
ModelArcs Blog

Model Registry + Validation Gate + Canary Deployment + Drift Telemetry + Audit Governance + Model Registry + Validation Gate + Canary Deployment + Drift Telemetry + Audit Governance +
Frequently Asked Questions

Got Questions? We Have Answers

Understand how ModelArcs integrates with your ML training pipelines, enforces automated gates, and ensures compliance.

ModelArcs integrates natively via lightweight Python SDK decorators and CI/CD webhooks. When training jobs in PyTorch, Kubeflow, Ray, or MLflow finish, ModelArcs automatically fingerprints model weights, dataset hashes, hyperparameters, and environment dependencies into an immutable registry record - requiring no structural refactoring of your ML training code.

A deployment gate is an automated policy checkpoint. Before a model can receive traffic, ModelArcs evaluates empirical validation evidence against strict criteria: accuracy thresholds, latency degradation, bias/fairness bounds, and security scans. If all conditions pass, ModelArcs signs a cryptographic token authorizing release; if any gate fails, deployment is automatically blocked.

ModelArcs streams live inference telemetry from Triton, TorchServe, or vLLM endpoints. It computes statistical divergence (Kolmogorov-Smirnov tests and Wasserstein distance) in real-time. If feature drift or prediction skew breaches defined safety margins during canary ramp-up (5% → 25%), ModelArcs instantly rolls back traffic to the previous verified model checkpoint in under 200ms.

Yes. ModelArcs is distributed as production-tested Kubernetes Helm charts. We support multi-cloud deployments across AWS EKS, GCP GKE, Azure AKS, as well as fully air-gapped on-premises OpenShift and bare-metal environments with zero external egress dependencies.

Get in Touch

Ready to Operationalize Your
AI Model Lifecycle?

Connect with our enterprise ML engineering team for a personalized platform demonstration or technical architecture assessment.

Talk to our team

Email, call, or send the form - we’ll help you get started.

Request a demo

We’ll get back to you within 2 business hours.

Your information is private and never shared.

Enterprise Model Lifecycle

A Connected Lifecycle. A Clearer Way to Operate.

ModelArcs connects registration, validation, release, deployment, production review, and retirement into one traceable model lifecycle - helping ML teams replace fragmented operational processes with a clearer, more accountable way to manage AI in production.

✓ One connected record for every model, owner, and dependency
✓ Visible validation, release, and production decisions
✓ Retirement with context, not guesswork

✦ No credit card required • Custom VPC deployment in under 48 hours

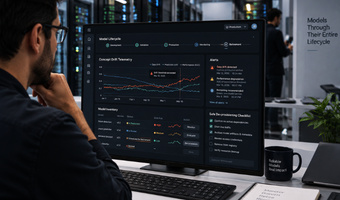
ML engineer with the ModelArcs lifecycle workspace
✦
100% Traceable Full Artifact Lineage
⚡
< 2s Rollback Automated Canary Gate